Series 1.1.4 - Evaluating logistic regression model in scikit-learn
Machine learning projects
Scikit-learn
Polars
Python
Jupyter
ChEMBL database
Cheminformatics
Author
Jennifer HY Lin
Published
January 4, 2023
Modified
November 1, 2024
Import libraries
In this fourth post and likely the last post of the logistic regression (LR) series, we’re still going to begin with importing all the libraries needed for the following work on model evaluations.
import sklearnprint(f"scikit-learn version used is: {sklearn.__version__}")from sklearn.model_selection import train_test_splitimport polars as plprint(f"polars version used is: {pl.__version__}")import pickleimport matplotlib.pyplot as pltfrom sklearn import metrics# For model evaluationsfrom sklearn.metrics import accuracy_score, confusion_matrix, ConfusionMatrixDisplay, classification_report, RocCurveDisplay, roc_curve, log_loss
scikit-learn version used is: 1.5.0
polars version used is: 1.9.0
Import logistic regression pipeline/model
Next, we need to load the pickled file so we can evaluate the same LR pipeline used last time.
In a Jupyter environment, please rerun this cell to show the HTML representation or trust the notebook. On GitHub, the HTML representation is unable to render, please try loading this page with nbviewer.org.
This part will involve using accuracy scores, confusion matrix, receiver operating characteristic (ROC) curve, classification report and log loss to evaluate the LR model. The main statistical principles and concepts being referred to here are mostly from this reference textbook (Bruce, Bruce, and Gedeck 2020), and a lot of native built-in functions from scikit-learn (Pedregosa et al. 2011) are used to generate the results.
Accuracy scores
The easiest one to understand will be accuracy score, which can be calculated using predicted y outcome and actual or true y outcome in scikit-learn as shown below.
## Read in data & split into training & testing setsdf = pl.read_csv("df_ml.csv")X = df["#RO5 Violations", "Polar Surface Area", "HBA", "HBD", "QED Weighted", "CX LogP", "CX LogD", "Heavy Atoms"]y = df["Max_Phase"]X_train, X_test, y_train, y_test = train_test_split(X, y, test_size =0.2, random_state =50)LR.fit(X_train, y_train)y_mp = LR.predict(X_test)accuracy_score(y_mp, y_test)## getting a warning message after accuracy score generated earlier # "UserWarning: X does not have valid feature names, but LogisticRegression was fitted with feature names" # - resolved, missed the fitting step first (my bad) before predict()
0.689594356261023
The accuracy score is 0.69 (after rounding up) which means that there are around 70% of the cases or compounds classified correctly by using the LR classifier. This score is also the same as the one shown from the previous post using score() instead of accuracy_score().
Accuracy score gives an idea about how close the predicted samples are to the true values. One caveat to note is that for imbalanced dataset, accuracy score might not be very informative and other evaluation metrics will be needed as well.
Confusion matrix
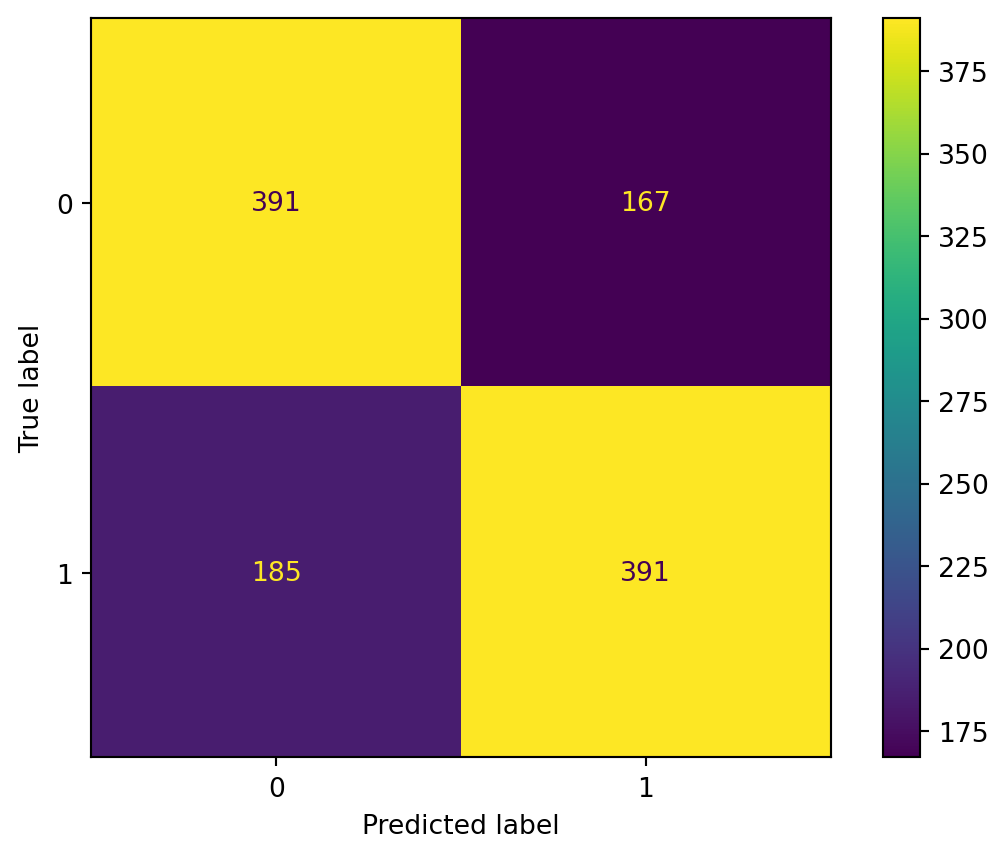
A confusion matrix is built below based on the model in order to visualise the counts of correct and incorrect predictions. Previous code used to plot confusion matrix is shown below:
Code
## Function to print and plot confusion matrix## The function code below was adapted from the IBM data science course I've taken previously# # to create iterators for efficient looping# import itertools# import numpy as np# def plot_confusion_matrix(# Sets a cm object (cm = confusion matrix)# cm, # # Sets classes of '1s' (Successes) & '0s' (Non-successes) for the cm# classes,# # If setting normalize = true, reports in ratios instead of counts# normalize,# title = 'Confusion matrix',# # Choose colour of the cm (using colourmap recognised by matplotlib)# cmap = plt.cm.Reds):# if normalize:# cm = cm.astype('float') / cm.sum(axis = 1)[:, np.newaxis]# print("Normalized confusion matrix")# else:# print('Confusion matrix, without normalization')# print(cm)# # Plot the confusion matrix # plt.imshow(cm, interpolation = 'nearest', cmap = cmap)# plt.title(title)# plt.colorbar()# tick_marks = np.arange(len(classes))# plt.xticks(tick_marks, classes, rotation = 45)# plt.yticks(tick_marks, classes)# # Floats to be round up to two decimal places if using normalize = True# # or else use integers# fmt = '.2f' if normalize else 'd'# # Sets threshold of 0.5# thresh = cm.max() / 2.# # Iterate through the results and differentiate between two text colours # # by using the threshold as a cut-off# for i, j in itertools.product(range(cm.shape[0]), range(cm.shape[1])):# plt.text(j, i, format(cm[i, j], fmt),# horizontalalignment = "center",# color = "white" if cm[i, j] > thresh else "black")# plt.tight_layout()# plt.ylabel('True label')# plt.xlabel('Predicted label')# # Compute confusion matrix# matrix = confusion_matrix(y_test, y_mp, labels = [0,1])# np.set_printoptions(precision = 2)# # Plot confusion matrix without normalisation# plt.figure()# plot_confusion_matrix(matrix, # # Define classes of outcomes# classes = ['Max_Phase = 0','Max_Phase = 1'], # # Set normalize = True if wanting ratios instead# normalize = False, # title = "Confusion matrix without normalisation"# )
There is actually an alternative and probably a better way (that uses less code) to plot confusion matrix using scikit-learn’s code as shown here:
A common rule of thumb for confusion matrix is that all predicted outcomes are columns and all the true outcomes are rows. However, there might be exceptions where this would be the other way round.
Four different categories can be seen in the confusion matrix:
True positive - Predicted Max_Phase = 1 & True Max_Phase = 1 (391) - interested in this
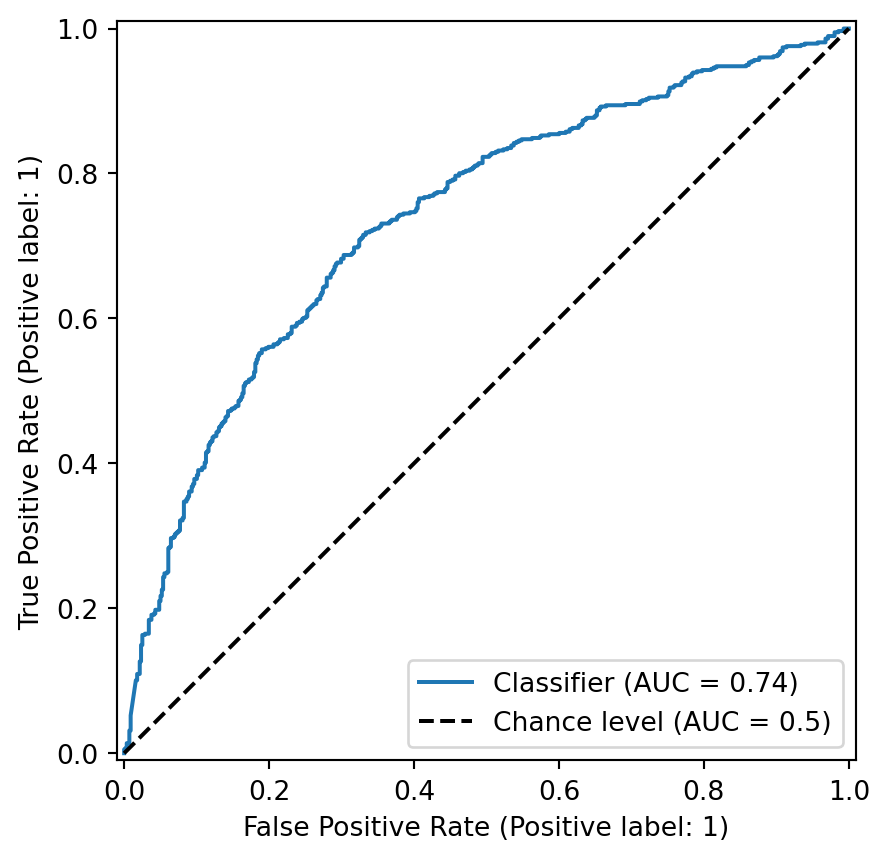
My old post about random forest classifier has already explained what an area under the ROC curve is (I’m just going to quote myself…):
Area under the ROC curve: reference - the area under a curve plot between sensitivity or recall (percent of all 1s classified correctly by a classifier or true positive rate) and specificity (percent of all 0s classified correctly by a classifier, or equivalent to 1 - false positive rate or true negative rate) (Bruce, Bruce, and Gedeck 2020). It is useful for evaluating the performance of a classification model via comparing the true positive rate and false positive rate which are influenced by shifting the decision threshold. Area under the ROC is usually represented as a number ranging from 0 to 1 (1 being a perfect classifier, 0.5 or below meaning a poor, ineffective classifier)
In this case, we can also apply ROC curve to the LR model and its predicted outcomes.
# get the predicted probabilities of outcome = 1 (approved drugs)y_mp_probs = LR.predict_proba(X_test)[:, 1]RocCurveDisplay.from_predictions(y_test, y_mp_probs, plot_chance_level =True)
<sklearn.metrics._plot.roc_curve.RocCurveDisplay at 0x12cfd02d0>
Precision is a measure of the accuracy of a predicted outcome, where a class label has been predicted by the classifier. In this case, we can see that for class label 1, the precision is 0.70, which corresponds to the true positive result of 391 out of 558 samples (= 0.70, for true predicted Max_Phase = 1 column). It is defined by:
Recall, also known as sensitivity (especially widely used in biostatistics and medical diagnostic fields), is a measure of the strength of the classifier to predict a positive outcome. In simple words, it measures the true positive rate. In this example, there is a total of 391 out of 576 samples (which = 0.68, for true Max_Phase = 1 row). It is defined by:
The precision and recall metrics are also calculated and shown for row 0 in the classification report.
f1-score, or also known as balanced F-score or F-measure, denoted the harmonic average of both precision and recall metrics. This metric will also give another indication about whether this model performed well on outcome predictions. Its range is normally from 0 (worst precision and recall) to 1 (perfect precision and recall). For this particular classifier, f1-score was at 0.69 (for class label = 1). It is defined as:
Support is the total number of true samples in each class label (reading row-wise from the confusion matrix). The main purpose of showing this metric is to help clarifying whether the model has had a reasonably balanced dataset for each class (and also helped to check the precision and recall values if needed).
Log loss
Log loss can be used as another metric to show how good the classifier is at making the predictions. The further apart the predicted probability is from the true value, the larger the log loss, which is also ranging from 0 to 1. Ideally, the smaller the log loss the better the model will be. Here, we have a log loss of 0.61 (after rounding up) for this particular model.
log_loss(y_test, y_mp_probs)
0.6097696128595831
Thoughts
So here I’ve completed a very basic LR classifier model for ChEMBL small molecules dataset. This is certainly not the most optimal machine learning model as I’ve only wanted to show how a baseline LR model can be built. This post update has added a molecular features versus coefficients plot (in the previous post) which shows the different weightings of the features used to train the dataset, ideally I should include more to provide a better overview of how the physicochemical properties will influence the prediction outcomes, but potentially this plot sort of answers the main goal of the post - which molecular properties might influence max phase outcomes. This last post here is really to show all the different evaluation metrics for the LR model, and I’ve added a ROC curve this time.
To further improve this model, I could possibly try hyperparameter tuning although I’ve come across comments from others in the past that it might not improve LR model that much once it’s done. Originally I do have two other posts following on from the first one (which is currently splitted into four smaller posts), and one of them is about hyperparameter tuning. My possible plan at the moment is to maybe update these other two posts further down the line and I may decide to condense or remove them if it’s not really going to make much difference or impact, I’ll see…
Acknowledgements
Huge thanks to our online open-source communities, libraries, and also all the references used in this series of posts.
Online references
I’ve listed below all the online references used throughout this project. All the other journal paper or text book references used should be cited in the post already or listed below.