Series 1.1.1 - Parquet file in Polars dataframe library
Machine learning projects
Polars
Python
Jupyter
ChEMBL database
Cheminformatics
Author
Jennifer HY Lin
Published
January 4, 2023
Modified
October 25, 2024
Why updating this post?
Three reasons for this:
ChEMBL data downloaded straight from the ChEMBL database website is way too large to be uploaded to GitHub - this is one of my very early posts where ChEMBL is completely new to me at the time so I’ve downloaded the ChEMBL data without thinking too much, obviously there are other better and more reproducible ways to source ChEMBL data e.g. my more recent posts or through other ways in the literatures
Note: GitHub blocks files larger than 100 MiB, which is in mebibytes and equivalent to 1,048,576 bytes or 1.04858 MB (reference) - my bad before as I’ve read “MiB” as “MB” from this GitHub doc!
Polars seems to be a bit more integrated with scikit-learn now so I’m wondering if Polars dataframe library can be used with scikit-learn solely (i.e. not using Pandas at all)
This post is one of my earlier less mature posts (very embarrassing when I’m looking at it now…) so I just want to improve it a little at least
Previous post updates
Update on 19th April 2024 - Polars is currently more integrated with scikit-learn from version 1.4 (since January 2024), see this link re. Polars output in set_output for Polars dataframe outputs in scikit-learn, and also a few other Polars enhancements from release version 1.4 changelog.
Update on 16th August 2023 - some code updates only, please always refer to Polars API reference for most up-to-date code.
Background
This is the first part of the series of posts on building a logistic regression model by using scikit-learn with Polars dataframe library (note: the older version of this post also uses Pandas). Polars is a fast (or more commonly known as “blazingly fast”) dataframe library that is written completely in Rust with a very light Python binding that is available for use in Python or Rust programming language. Here I’ll be using Python throughout all posts in the series.
This post will only focus on getting the small molecules data ready from ChEMBL database via a straight website download (not recommended if you’re researching or doing virtual experiments that require a good level of data reproducibility, e.g. you’ll need the version of data etc., this is however only a demonstration so I’ll leave it as it is), and then convert the comma separated value (.csv) file into a parquet file (for better file compressions) in order to upload the data into GitHub.
Install and import Polars
## To install Polars dataframe library (or install in virtual environments)#%pip install polars## Update Polars version#%pip install --upgrade polarsimport polars as plpl.show_versions()
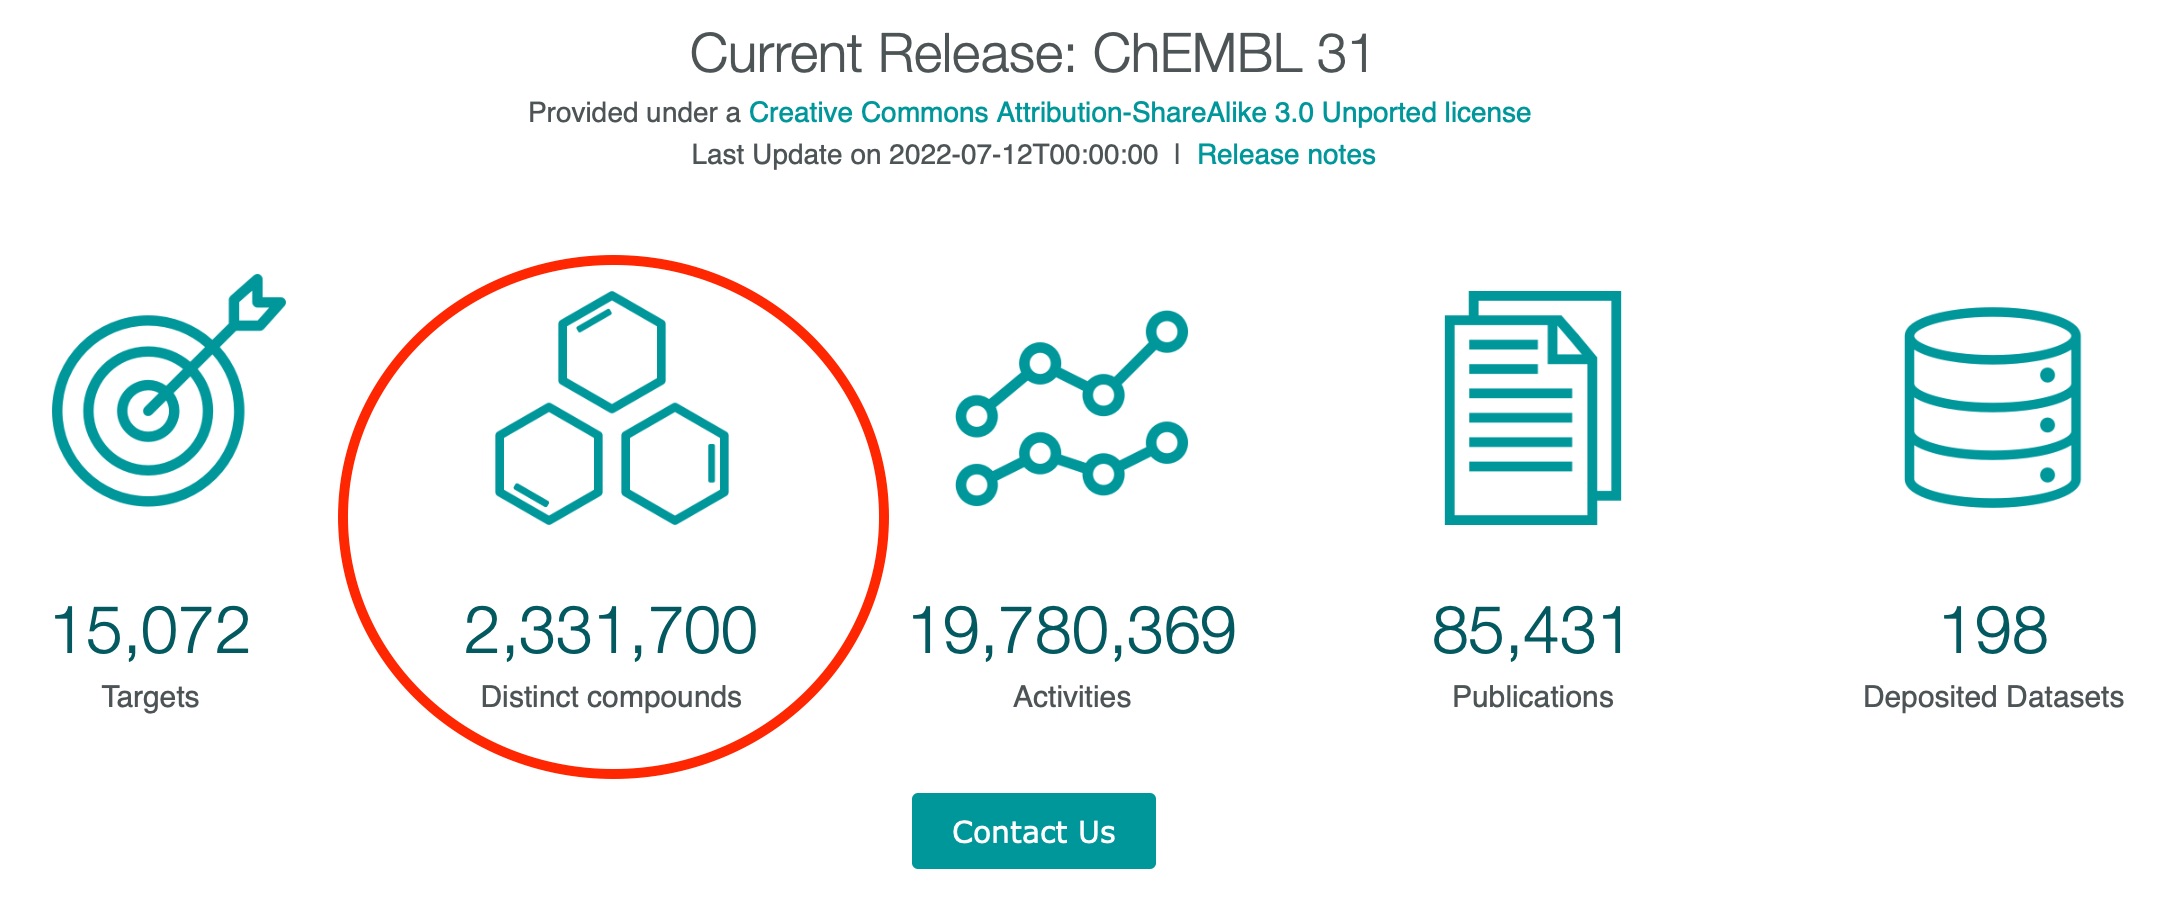
The file being used here will be equivalent to a straight download from the home page of ChEMBL database, via clicking on the “Distinct compounds” (see the circled area in the image below). Options are available to download the files as .csv, .tsv or .sdf formats (located at the top right of the page).
Image adapted from ChEMBL database website at version 31
I’m reading the .csv file first to have an overall look at the data.
Some data wrangling and converting a csv file into a parquet file
A .csv file tends to be separated by delimiters e.g. commas, semicolons or tabs. To read it properly, we can add a delimiter term in the code to transform the dataframe into a more readable format.
Another thing being added below is to deal with null values early - by filling in “None” and “” values in the dataframe as “null” first. This will save some hassles later on (I’ve encountered this problem when trying to convert column data types so found out this may be the best way to resolve it).
Below is a series of data checks and cleaning that’ll reduce the original .csv file size (about 664.8 MB) into something more manageable. My goal is to get a parquet file under 104 MB which can then be uploaded to GitHub without using Git large file storage (this will be the last resort if this fails).
I’m checking the “Type” column first.
df.group_by("Type").len()
shape: (11, 2)
Type
len
str
u32
"Unknown"
18015
null
369155
"Cell"
47
"Gene"
77
"Oligonucleotide"
170
…
…
"Antibody"
974
"Enzyme"
118
"Small molecule"
1920366
"Oligosaccharide"
92
"Unclassified"
4
The dataframe is further reduced in size by filtering the data for small molecules only, which are what I aim to look at.
There are 5485 entries with “NONE” as “Structure Type” which means they have unknown compound structures or not recorded in either compound_structures table or protein_therapeutics table. These entries will be removed from df_sm first.
Next, I’m filtering the df_sm dataset further by restricting the filters to only small molecules and excluding all “NONE” structure types.
# Check "NONE" entries are removed/filtereddf_sm.group_by("Structure Type").len()
shape: (3, 2)
Structure Type
len
str
u32
"SEQ"
1
"MOL"
1914876
"BOTH"
4
I’ve tried filtering out data using “Inorganic flag” previously, however it turns out to be not so suitable - it’ll rule out a lot of preclinical compounds with max phase 0 or max phase > 1 compounds with no calculated physicochemical properties, which means there may not be enough training data to build a machine learning model. So I’m opting for the “Targets” column here by ruling out the ones with zero targets.
I have tried two main different ways where one is using the write_parquet() by only adding file compression level parameter (the “without partition” way), and the other one using use_pyarrow & pyarrow_options to partition datasets. The changes in parquet file size are shown in the following two tables.
Parquet file size changes with data partitions (note: original .csv file size is 664.8 MB)
Compression level
Data restrictions
File size
Number of entries
default
None
using “Max Phase” as partition column
max phase 0 > 104 MB
max phases 1-4: each < 104 MB
2,331,700
15
None
max phase 0 > 104 MB
max phase 1-4: each < 104 MB
2,331,700
20
None
similar sizes as mentioned above
2,331,700
default
None
using “Type” as partition column
“Small molecule” file size = 135.2 MB
2,331,700
Finally, it appears that the one with three data restrictions at compression level of 22 has produced a file at 100.4 MB. I’m reading this file below into a dataframe to see if it’s working.
So it looks like it does. The next series of posts will be about trying to use Polars dataframe library all the way with scikit-learn.
Note: the way I’ve compressed the original data file may not be the best as I’m losing some data along the way by restricting the number of data entries. There are definitely other better ways out there, please use this example with care.